gymnasium a.k.a gym
gym: 오픈AI가 개발한 강화학습 환경을 위한 라이브러리
2021년부터 gymnasium으로 포크하여 Farama 재단이 관리
설치
임포트
대부분의 자료가 여전히 gym을 기준으로 작성되어 있으므로, gymnasium의 이름을 gym으로 임포트
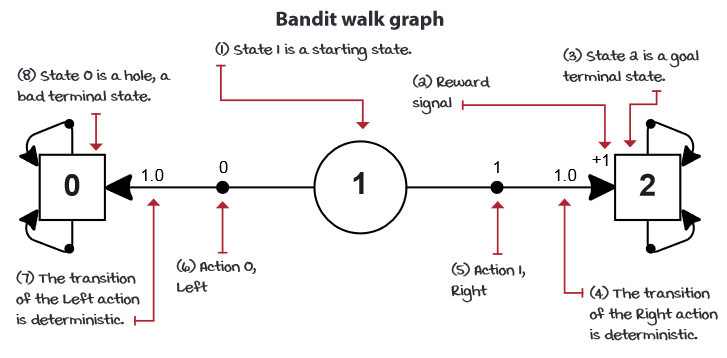
밴딧 보행 bandit walk
밴딧 환경: 끝나지 않는(non-terminal) 상태가 오직 1개인 환경
밴딧 보행에서는 왼쪽-오른쪽 2가지 행동만 가능
시작 상태는 항상 가운데(상태 1)
결정론적 전이 함수: 왼쪽으로 가면(행동) 왼쪽으로 가고(다음 상태), 오른쪽으로 가면 오른쪽으로 감
왼쪽 상태 0에 도달하면 보상 0을 받고 종료
오른쪽 상태 2에 도달하면 보상 +1을 받고 종료
격자 세계 grid world
2차원 격자(grid) 형태의 환경
행위자가 할 수 있는 행동이 좌우 또는 동서남북 형태인 종류의 환경
강화학습 교육 및 연구에서 예제로 흔히 사용
밴딧 보행은 격자 세계를 사용
밴딧 보행 환경 구현하기
class BanditWalk (gym.Env):
def __init__ (self ):
self.action_space = gym.spaces.Discrete(2 )
self.observation_space = gym.spaces.Discrete(3 )
self.state = 1
def reset (self ):
self.state = 1
return self.state, {}
def step (self, action ):
if action == 0 :
reward = 0
self.state = 0
else :
reward = 1
self.state = 2
return self.state, reward, True , False , {}
Discrete
Discrete(2 )
Discrete(3 , start=-1 )
space = gym.spaces.Discrete(2 )
for _ in range (10 ):
print (space.sample())
MultiDiscrete
Box
Box(low=-1.0 , high=2.0 , shape=(3 , 4 ), dtype=np.float32)
Box(low=np.array([-1.0 , -2.0 ]), high=np.array([2.0 , 4.0 ]), dtype=np.float32)
low: 구간의 하한
high: 구간의 상한
shape: 모양은 기본적으로 (1,)
dtype: 자료형
무작위 전략
env = BanditWalk()
returns = []
for i in range (100 ):
env.reset()
terminated = False
while not terminated:
action = env.action_space.sample()
obs, reward, terminated, truncated, info = env.step(action)
else :
returns.append(reward)
import numpy as np
np.mean(returns)
버전 간 차이
reset: gym 신버전은 info를 반환하도록 변경
obs = env.reset()
obs, info = env.reset()
step: gym 신버전은 done을 terminated와 truncated로 구분
obs, reward, done, info = env.step(action)
obs, reward, terminated, truncated, info = env.step(action)
책, 인터넷 등에 구버전 기준으로 되어 있는 자료들이 많으므로 주의가 필요